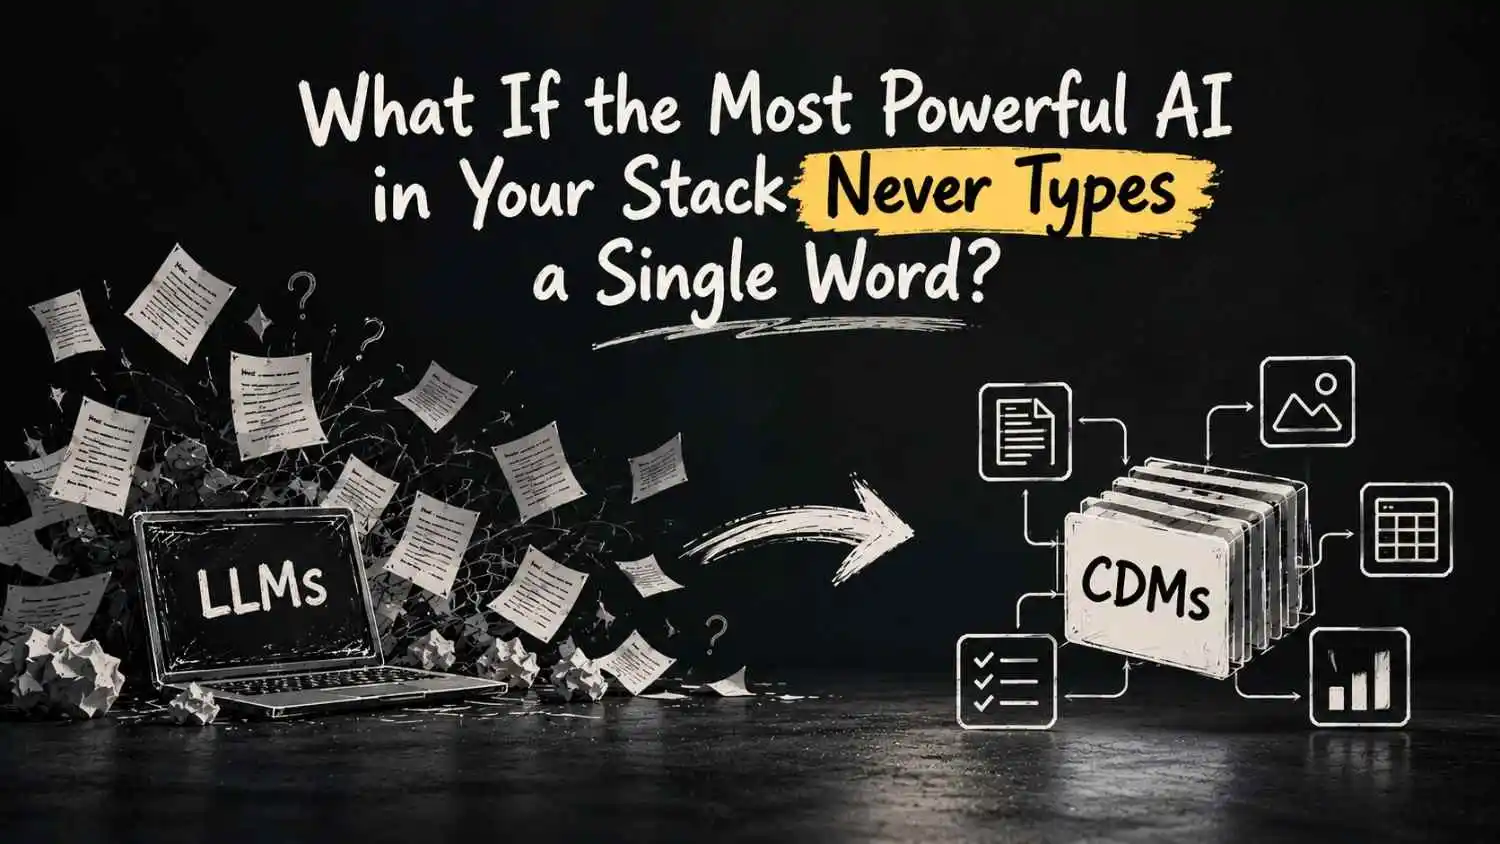
Maximizing AI ROI with Constrained Decoding Models (CDMs)
At 3:14 AM on a Tuesday, an unescaped double quote slipped into a production loan workflow. A standard language model was extracting customer income and credit figures from uploaded PDFs, parsing hundreds of records per minute. Everything looked green on the surface. But inside the pipeline, the downstream JSON parser hit an unexpected quotation mark and quietly discarded the field. By sunrise, 14,000 recursive retry loops had fired across the cluster, burning through $18,400 in redundant API tokens while eleven customer loan decisions sat silently corrupted in the database. The model was capable. The syntax parser was unforgiving. Here is the engineering reality behind Constrained Decoding Models (CDMs) and how runtime token masking turns chaotic output distributions into deterministic enterprise execution.
Why Constrained Decoding Models (CDMs) Decide Your AI ROI
The Hidden Tax of Autoregressive Generation in Enterprise AI
When an enterprise workflow needs to route a customer inquiry into one of five departments, pull a renewal date out of a 60-page vendor agreement, or strip noisy HTML from a web scrape before an AI agent reads it, traditional architectures call a general-purpose LLM. Every time that call happens, your system pays an invisible architectural penalty.
Even though the exact text or label you need is already present in your input payload, a generative LLM treats the task like an open-ended writing prompt. It reads your input in a parallel prefill pass, then enters an autoregressive decoding loop, generating the response one token at a time. Each token must wait for the previous token to clear memory bandwidth. Because autoregressive output generation is computationally memory-bound, cloud providers charge 3x to 5x more for output tokens than input tokens. You end up paying flagship prices just for a massive model to echo back strings from your own document.
The Golden Rule of Token Economics
Structured Outputs vs. CDMs: Inference Guardrails vs. Dedicated Models
When evaluating structured generation in 2026, engineering leaders often encounter two distinct technologies sharing similar terminology. Separating them is essential for designing your stack:
Layer 1: Constrained Decoding Engines (Runtime Inference Guardrails)
Open-source engines like XGrammar (integrated natively into vLLM and SGLang), Outlines, and Microsoft's Guidance (llguidance) sit on top of standard chat models. As the LLM generates text token by token, these engines apply a state machine or precomputed bitmask over the vocabulary. Any token that would violate your target JSON schema or regular expression has its probability set to zero (-inf logit). • What it solves: Makes broken JSON or invalid syntax mathematically impossible. • What it does not solve: The underlying LLM is still running a heavy, token-by-token generation loop.
Layer 2: Constrained Decoding Models / CDMs (Task-Specific Model Class)
Pioneered as a dedicated model category by ScaleDown (alongside decision-model peers like TypeSafe AI's Jev and Liquid AI's d1) and deployed across enterprise agent harnesses by Starling Elevate, a CDM is not a syntax mask bolted onto a general chatbot. It is a specialized model trained for bounded operational primitives (classification, extraction, summarization, and context compression) where the output space is strictly governed by the input.
Action Required: Auditing Your Current Spend
Why does a CDM execute up to 200x faster than a general LLM on routine workflow tasks? Look at the execution mechanics across the four core CDM primitives:
• Deterministic Classification ( Classify ): Instead of generating characters like "B", "i", "l", "l", "i", "n", "g" inside a JSON block, you pass your input alongside candidate labels and a one-line rubric for each. In a single forward pass, the CDM scores the input against every rubric simultaneously, returning the top_label, a calibrated probability map ( scores summing to 1.0), and a one-sentence audit trail.
• Verbatim Span Pointing ( Extract ): When a generative LLM extracts an invoice total or clinical code, it re-types the string, creating a constant risk of hallucinated digits. An extraction CDM points directly to the exact character start and end offsets in your source document. It returns the verbatim slice, 500 characters of surrounding context, and a confidence score. If your schema includes a categorical or boolean field alongside text spans, it automatically routes that specific key to the classification engine via enum or oneOf rules.
• High-Capacity Context Pruning ( Compress & Summarize ): Built with 1-million-token multimodal context windows (supporting text, tables, and base64 PDFs/images), Compress strips irrelevant boilerplate from raw tool outputs before your primary LLM reads them, while Summarize condenses sprawling agent message histories into structured state summaries.
Generative LLMs vs. Decision Models (Jev) vs. CDMs
To choose the right model class for each stage of your pipeline, compare the three paradigms operating in enterprise stacks today:
| Feature / Attribute | LLM (Generative) | Jev (Decision Model) | CDM (Constrained Decoding Model) |
|---|---|---|---|
| Primary Function | Open-ended text generation, creative writing, multi-step code and reasoning | Pure statistical judgment (Choice, Score, Binary/Null) | Structured classification, extraction pointing, and context management |
| Output Type | Natural language prose / code (Token-by-token generation) | Typed numbers, probabilities, confidence scores, and enumerations only | Verbatim text spans, character offsets, confidence maps, and probability distributions |
| Can it summarize or write text? | Yes (Native capability) | No (Strictly forbidden by design) | Yes (Dedicated context modules like Summarize and Compress) |
| Input Modality | Multimodal (Text, Images, Audio, Video, PDFs) | Text only (Strings, JSON objects, or arrays) | High-capacity multimodal (Up to 1M tokens: text, tables, base64 PDFs/images) |
| Output Token Cost | Expensive ($0.60 to $15.00+ per 1M tokens) | Free ($0.00 output structure) | Free ($0.00 output structure) |
| Ideal Use Case | Complex agent reasoning, chatbot interfaces, final user-facing text | High-frequency routing, boolean flags, risk scoring, alert triage | Document data extraction, context window pruning, tool output compression |
Unit Economics & Benchmark Reality: General LLMs vs. Specialized CDMs
When scaling an AI product from a 50-user pilot to 50,000 daily production runs, token economics determine whether your gross margins survive.
| Operational Metric | Frontier & Mini LLMs (GPT-4o mini / Claude 3.5 Sonnet / GPT-6 Luna) | Constrained Decoding Models (ScaleDown CDM Suite) |
|---|---|---|
| Core Mechanism | Autoregressive token-by-token generation | Constrained space scoring & span pointing |
| Input Pricing | $0.15 to $3.00+ per 1M input tokens | $0.04 to $0.05 per 1M input tokens |
| Output Pricing | $0.60 to $15.00+ per 1M output tokens | $0.00 (Output is completely free) |
| Context Window | 128K to 1M tokens (cost scales steeply) | Up to 1,000,000 tokens (Text + Images/PDFs) |
| Accuracy (DecisionBench / Enterprise) | Baseline (prone to format drift without masks) | +8.72% higher average accuracy vs. general mini models (77.2% on DecisionBench) |
| Speed & Cost Efficiency | High Time-to-Last-Token on long outputs | 2.4x to 200x faster; 89x to 467x cheaper overall |
Consider a real-world enterprise workload: summarizing and extracting metadata from 10,000 customer operations tickets every day. Running that volume through a standard commercial LLM API costs upwards of $58+ per day. Routing the exact same workload through a CDM with $0 output token pricing and $0.05 per million input tokens drops the daily compute bill to $7.20, and in pure classification workloads, cost reductions exceed 5,000x compared to large frontier models.
The Hub-and-Spoke Pattern: Where CDMs Fit in Your Production Stack
CDMs are not built to replace your frontier LLM. If your workflow requires complex code generation, nuanced legal drafting, or open-ended strategy synthesis, a CDM is the wrong tool. In fact, 2026 benchmarks on structured generation highlight an important architectural boundary: while constrained decoding eliminates 100% of schema syntax failures, forcing a model to perform deep multi-step reasoning inside a rigid schema without a prior "thinking" pass restricts its problem-solving accuracy. At Starling Elevate, we architect production systems around the Hub-and-Spoke Pattern:
The Hub-and-Spoke Architecture

The Reasoning Hub (Frontier LLM)
Positioned at the center to handle complex synthesis, multi-step planning, and final user-facing responses.
The CDM Spokes (Deterministic Middleware)
Surrounding the main model to absorb repetitive, high-token chores on every turn.
In long-running autonomous agents, context bloat is the primary cause of both latency spikes and runaway API bills. Placing CDMs in your agent harness solves four critical bottlenecks:
Four Critical Agent Bottlenecks Solved by CDMs
Step 1: Tool Output Compression
Strip noisy JSON payloads, SQL dumps, and web scrapes down to relevant facts before your primary LLM ingests them.
Step 2: Automated Context Summarization
Trigger background history compression the moment an agent session crosses 75% of its context window.
Step 3: Real-Time Loop & Drift Detection
Score agent trajectory on every turn using Classify to halt runaway loops if a "looping" rubric crosses a 0.8 probability threshold.
Step 4: Zero-Hallucination State Extraction
Pull structured entities straight from user documents into your ERP or CRM database at $0 output token cost.
Production Implementation: Enterprise ERP & Compliance Agent
You do not need to rebuild your application from scratch to adopt this architecture. CDMs integrate natively with LangChain, Deep Agents, OpenRouter, LiteLLM, and Vercel AI Gateway. Below is a production implementation showing how to wire three CDM middlewares into an enterprise procurement and ERP compliance agent:
Open-Source Token Masking & Production Pitfalls
For organizations in healthcare, finance, or legal tech that require deploying open-weights models (such as Llama 3.2, Qwen3, or Phi-4-mini) on private cloud servers, pairing local inference with open-source constrained decoding engines is mandatory.
How XGrammar Eliminates Runtime Masking Latency
Early constrained decoding libraries compiled regex and JSON schemas dynamically on the CPU during each token step, adding hundreds of milliseconds of latency. Modern engines like XGrammar (built into vLLM and SGLang) divide vocabulary tokens into context-independent and context-dependent caches offline. At runtime, a specialized GPU bitset kernel checks token validity in under 40 microseconds, delivering 100% schema adherence with virtually zero latency overhead.
3 Common Mistakes When Deploying Constrained Decoding
- The Mistake: Assuming 'Schema-Valid' Means 'Factually Correct'
- Why it hurts: Constrained decoding guarantees that a field is an integer or valid JSON, but if you use a standard generative model instead of a pointer-based CDM, the model can still hallucinate the number itself.
- The Smart Fix: Use pointer-based extraction CDMs that return exact character offsets (
startandend) verified against the source document.
- The Mistake: Forcing Complex Math or Logic into Constrained Enums
- Why it hurts: Token masking restricts the model's intermediate 'thinking' tokens, causing accuracy to drop on multi-step logic problems.
- The Smart Fix: Either allow a brief reasoning step prior to the constrained decision field or offload pure classification/extraction to a dedicated CDM while keeping complex reasoning in your hub LLM.
- The Mistake: Recompiling Complex JSON Schemas on Every API Request
- Why it hurts: Dynamic grammar compilation spikes CPU utilization under concurrent traffic.
- The Smart Fix: Pre-register static schemas in your inference gateway or use managed CDM endpoints where rubrics and schemas are optimized at the protocol layer.
Key Takeaways on Modernizing Your AI Infrastructure
- Stop Paying Output Prices for Input Data
Whenever the target output is a label from a fixed list or a text span inside your document, generative token-by-token writing wastes both time and budget.
- Combine Hub Reasoning with Spoke Efficiency
Keep frontier LLMs for complex synthesis and surround them with CDMs for classification, extraction, tool compression, and history summarization.
- Cut Ongoing AI Bills by 60-85%+
At $0.04 to $0.05 per 1M input tokens and $0.00 output costs, CDMs transform unit economics for high-volume enterprise pipelines.
- Deploy in Minutes
Whether through drop-in LangChain middleware, API routers like OpenRouter and LiteLLM, or self-hosted vLLM instances running XGrammar, your team can integrate constrained decoding without re-architecting your application.
Build Production-Ready, Cost-Optimized AI with Starling Elevate
Starling Elevate is not a generic software agency that recently bolted "AI" onto its service page. We are a specialized AI engineering company focused on building production-grade multi-agent systems, OCR and document extraction pipelines, and token-optimized enterprise architectures that deliver measurable ROI. Whether you need to cut your monthly LLM API spend by 60 to 85% through intelligent model routing and CDMs, or deploy private, sub-150ms open-source models inside your own cloud environment, our AI engineering team is ready to help.
Ready to slash enterprise token costs and build deterministic AI pipelines?
Book a Free Discovery CallFrequently Asked Questions
A Constrained Decoding Model (CDM) is a task-specific AI model trained for bounded operations (such as classification, verbatim data extraction, summarization, and context compression) where the valid output space is constrained by the input document or schema. Unlike general LLMs that generate text token by token, CDMs score rubrics or point to exact character offsets in a single pass.
Table Of Contents
Tags
Driving Innovation and Impact
With engineering leadership and a proven delivery model, our journey is marked by a relentless pursuit of excellence and a commitment to driving measurable ROI for our clients across 10+ diverse industries.
Let's Connect