Expert Prompt Engineering Service for Maximize AI Performance
Transform how your business works with premier LLM prompt engineering services that drive accuracy, consistency, and real results across ChatGPT, Gemini, Claude, Copilot, and every major LLM.
At Starling Elevate, we specialize in comprehensive AI prompt engineering services and prompt engineering services designed for businesses, developers, and enterprises ready to unlock the full potential of generative AI. Whether you're building AI-powered products, automating internal workflows, or deploying intelligent agents, the quality of your prompts determines the quality of your outcomes.
Higher Output Precision
AI Workflows Deployed
Fewer Hallucinations
LLM Token Cost Reduction through Instruction Pruning

Prompt Engineering Built for System Accuracy
Unstructured text prompts fail in enterprise environments. When deployed to customer-facing channels or core operations, consumer-grade prompting leads to unpredictable JSON schemas, logic drift, hallucinated facts, and uncontrolled API token spend. Industry benchmarks show that ambiguous instructions cause up to 73% of commercial LLM hallucinations. Simple zero-shot prompts cannot guarantee reliability under live user traffic.
Enterprise prompt engineering establishes structured engineering frameworks. Independent prompt architecture benchmarks demonstrate that structured System-Task-Context-Output (STCO) prompt design improves output accuracy by 31.9% to 42.4% on latest frontier reasoning models (such as GPT-6 Astra, Claude Sonnet 5, Gemini 3.1 Pro, and DeepSeek V4) compared to earlier generations (like GPT-4 and Claude 3.5) and unstructured prompts. Furthermore, algorithmic context pruning reduces token consumption by 60% to 80% without degrading response quality.
As a dedicated prompt engineering company, Starling Elevate engineers deterministic prompt architectures tailored to your backend systems. We structure clear instruction hierarchies, role constraints, negative constraints, and few-shot reasoning paths. Integrating directly with your vector stores, relational databases, and enterprise APIs, our pipelines ground every response in verified operational truth.
Prompt quality is validated programmatically before deployment. We build automated regression test suites using DSPy, TruLens, and LangSmith to evaluate faithfulness, semantic drift, and schema compliance across hundreds of edge-case queries. When foundation models update, our version-controlled prompt repositories ensure downstream workflows remain unbroken.
Every engagement delivers production-grade system prompts, modular few-shot libraries, Pydantic-enforced output schemas, automated regression benchmarks, and real-time guardrail architectures ready for integration into your CRM, ERP, or internal microservices.
A Systematic Stage Framework for Enterprise Prompt Architecture
Through end-to-end enterprise prompt engineering and structured prompt engineering services, we transform experimental generative AI into reliable software infrastructure through structured prompt design, automated evaluations, context retrieval grounding, and runtime guardrails.
Workflow Audit & Baseline Evaluation
We analyze your operational use cases, failure modes, and user queries. Using initial benchmark datasets, we measure baseline accuracy, hallucination frequency, latency, and token expenditure across candidate models.
Prompt Architecture & Structured Reasoning Design
We construct modular system prompts utilizing System-Task-Context-Output (STCO) hierarchies, dynamic variables, and chain-of-thought (CoT) reasoning paths, backed by curated few-shot demonstration sets for complex edge cases.
Context Engineering & Enterprise RAG Grounding
We connect prompts to knowledge stores, vector databases (Pinecone, Qdrant, Weaviate), and REST APIs. Prompts are optimized with dynamic chunk re-ranking and context pruning to eliminate irrelevant tokens and prevent context dilution.
Programmatic Testing, Optimization & Cost Reduction
Using evaluation frameworks like DSPy and TruLens, we run synthetic and ground-truth test suites across thousands of permutations, compressing prompt lengths to cut token costs by 30% to 50% while enforcing strict Pydantic JSON schemas.
Guardrail Deployment, Telemetry & Version Control
We deploy defense-in-depth guardrails against prompt injection and jailbreaks. Final prompt assets are committed to Git-backed repositories with automated CI/CD evaluation pipelines, semantic drift monitors, and observability hooks.
Production prompt architectures for critical operations
Prompt systems matter most where query variability is high and incorrect outputs create operational, financial, or compliance risks. Key environments include customer service copilots, clinical document extraction, financial reporting pipelines, and automated legal contract analysis.
Our AI prompt engineering services couple dynamic context injection with strict negative constraints and automated schema validation, ensuring language models behave with predictable determinism across complex enterprise workflows.
What This Enables:
- High-accuracy responses across customer-facing chatbots and internal employee copilots.
- Context-aware outputs grounded in live vector databases and enterprise knowledge repositories.
- Deterministic JSON schema enforcement for automated downstream ERP and CRM workflows.
- Up to 45% lower hallucination rates through multi-layer verification and grounding filters.
- Robust defense-in-depth against prompt injection attacks and malicious jailbreaks.
Measurable Business Impact of Prompt Engineering
Structured prompt systems turn probabilistic language models into dependable, high-ROI enterprise infrastructure. Systematic prompt optimization lowers recurring token costs, prevents hallucinations, and enforces deterministic data schemas across production teams.
What This Enables:
65%+ Output Precision with context-aware generation grounded in live enterprise databases
Deterministic JSON schema enforcement for direct automated ERP and CRM pipeline workflows
30% to 50% reduction in API token costs through systematic prompt pruning and compression
Defense-in-depth security guarding against prompt injections and malicious jailbreak attempts
Repeatable CI/CD evaluation benchmarks preventing performance regressions during model upgrades
Context-aware AI prompt solutions
Through our LLM prompt engineering services, you receive version-controlled prompt repositories, automated evaluation benchmarks, Pydantic data schemas, and production-grade guardrails designed for seamless, predictable AI behavior across your enterprise software stack.
Intelligent Prompt Frameworks
Structured prompt architectures that control how AI interprets instructions and generates consistent outputs across workflows.


Trusted AI prompt engineering
Choosing the right prompt engineering company matters when AI outputs affect customer trust, data integrity, and daily decisions. Starling Elevate delivers trusted prompt engineering services and production-grade generative AI infrastructure that integrates directly into your Workflow Automation and connected enterprise systems.
What Makes Our Approach Different
Engineering-First Methodology
We treat prompts as production software code: modular, Git version-controlled, tested against regression datasets, and maintained through continuous CI/CD evaluation pipelines.
Model-Agnostic Optimization
We build and optimize across OpenAI (GPT-6 Astra, GPT-5.6), Anthropic (Claude Sonnet 5, Opus 5), Google (Gemini 3.1 Pro, Gemini 3.8 Flash), DeepSeek V4, and open-weights architectures like Llama 4.
Enterprise Security & Compliance
We implement defense-in-depth sanitization, PII masking delimiters, and zero-data-retention API configs, with HIPAA-aligned prompt architectures proven in live deployments.
Seamless Enterprise Connectivity
Direct integrations with vector stores (Pinecone, Qdrant), knowledge graphs, relational databases, CRMs, and internal REST APIs keep AI embedded in daily operations.
Global Delivery Footprint
Validated production AI implementations delivered for clients across the United States, United Kingdom, Malaysia, Singapore, and Dubai.
Token Economics & Measurable ROI
Systematic prompt compression, dynamic few-shot retrieval, and caching ensure your generative AI systems scale with 30% to 50% lower API spend.
Advanced Model Orchestration Stack
Our prompt engineering stack combines LLM platforms, vector retrieval, evaluation tools, and orchestration frameworks for production AI systems.







AI Prompt Integrations Built for
Business Operations
We connect prompt systems to your databases, apps, APIs, and workflow tools so AI outputs reflect live business data. Integrations keep AI inside existing processes instead of isolated chat windows. Teams get faster execution, fewer manual handoffs, and outputs that trigger real actions.
Data & Knowledge Layer Integration
Connect AI to databases, knowledge bases, and vector stores for context-grounded responses from verified information.
Application & User Experience Integration
Embed AI in web apps, mobile platforms, and dashboards for consistent real-time interaction across touchpoints.
Workflow & AI Orchestration
Operationalize prompt logic in multi-step workflows so outputs stay structured and actionable inside business processes.
API & Enterprise System Connectivity
Secure API integrations with CRMs, SaaS tools, and internal systems for continuous data exchange and aligned AI performance.
Optimize Your AI Integration with Expert Support
Get guided support for prompt design, model selection, and rollout planning so your AI projects reach production with confidence.
No Middlemen
Skip support queue and talk directly with the decision makers.
Align Faster
Share your goals, challenges, and priorities get aligned instantly.
Better Solutions
Get expert insights and tailored guidance for your unique integrations.
Build Trust
Transparent conversations that build long-term partnerships.
Ready to Connect?
Book a one-on-one call with our CEO or CTO.


100+ business trust our experts for seamless integrations.
AI Prompt Engineering Across Industries
Tested prompt pipelines powering HIPAA-compliant healthcare coordination, auditable financial analysis, high-conversion commerce, and multi-jurisdiction contract review.
Digital Healthcare Intelligence
Clinical documentation and care coordination prompts engineered with Claude Sonnet 5, clinical NLP engines, and HIPAA-compliant data controls deployed in Malaysia.
View Case Study
Adaptive Commerce Platforms
Multi-agent prompt orchestration and dynamic few-shot catalog prompts built with LangGraph for personalized merchandising and on-brand shopper support in the USA.
View Case Study
Intelligent Financial Operations
RAG-grounded prompt architectures enforcing strict numerical extraction, regulatory alignment, and auditable reasoning steps deployed for finance teams in the UK.
View Case Study
Legal Intelligence Platforms
AWS Bedrock and Claude prompt pipelines enforcing clause citation, adverse liability risk scoring, and NDA review deployed for legal firms in Dubai.
View Case Study
Smart Property Operations
RAG-connected property listing generation, automated tenant inquiry triage, and real-time buyer lead qualification prompts integrated with CRMs in Singapore.
View Case StudyFrequently Asked Questions
Didn't get an answer?
We will reach out to you in less than 2 hours!
Basic prompting relies on ad-hoc conversational queries in consumer chat interfaces. Enterprise prompt engineering builds programmatic, version-controlled instruction frameworks. It incorporates System-Task-Context-Output (STCO) hierarchies, dynamic few-shot demonstration sets, vector context injection, and automated evaluation suites to ensure deterministic, production-grade model behavior across business applications.
Few-shot prompting provides curated input-output demonstrations that teach models expected structure, tone, and edge-case handling. Chain-of-thought (CoT) prompting guides models to execute intermediate logical steps before answering. Together, these techniques reduce reasoning errors, improve output precision by over 65%, and prevent premature conclusions in multi-step workflows.
Context engineering formats, ranks, and filters external reference data retrieved from vector stores and enterprise databases before passing it to the LLM. In RAG pipelines, it ensures prompts contain only relevant, high-density document chunks. This prevents context dilution, reduces token expenditure, and grounds model answers in verified facts.
We construct automated evaluation test suites using frameworks like DSPy, TruLens, and LangSmith. Prompts are scored programmatically against ground-truth datasets for faithfulness, answer relevance, semantic drift, and schema validity. This testing ensures model updates or prompt edits never cause unexpected performance regressions in live production environments.
We compress verbose system instructions, prune low-information tokens, implement few-shot example dynamic retrieval, and replace conversational filler with compact structural templates. This methodology systematically reduces input token counts by 30% to 50% without degrading answer quality, drastically cutting monthly LLM operational expenses at enterprise scale.
We implement defense-in-depth guardrails combining strict role-delimiter boundaries, input sanitization layers, negative constraints, and secondary LLM validation checks. These defenses identify and neutralize adversarial jailbreak attempts, system prompt extraction queries, and unauthorized tool-calling requests before they reach your internal application logic or data stores.
Yes. We configure prompts with explicit Pydantic type definitions, key-value constraints, and provider-specific JSON mode flags. This forces models to return 100% deterministic, type-safe JSON payloads. Outputs validate against your API specifications for direct, reliable ingestion into enterprise databases, CRMs, and automated workflow pipelines.
When migrating from earlier architectures (such as GPT-4 or Claude 3.5) to next-generation frontier models (like GPT-6 Astra, Claude Sonnet 5, and Gemini 3.1 Pro), models respond differently to prompt nuances and reasoning tokens. We maintain provider-agnostic evaluation suites and model-specific variations to prevent performance regressions.
A focused prompt audit and benchmark pilot typically takes 2 to 4 weeks. Full enterprise implementations—spanning custom prompt architecture, RAG grounding, automated DSPy test suites, and CRM/ERP integrations—generally take 3 to 5 months depending on workflow complexity and compliance requirements.
We support commercial and open-source models including OpenAI GPT-6 Astra / GPT-5.6, Anthropic Claude Sonnet 5 / Opus 5, Google Gemini 3.1 Pro / 3.8 Flash, DeepSeek V4, and Llama 4. Our engineers build using orchestration frameworks like DSPy, LangChain, LlamaIndex, TruLens, and vector databases like Pinecone and Qdrant.
Engagement pricing depends on the number of unique AI workflows, target model architectures, RAG integration requirements, and security compliance standards. Projects are delivered via fixed-scope sprint milestones or dedicated forward-deployed engineering teams.
We build CI/CD evaluation pipelines that automatically test your prompt repository whenever an LLM vendor releases a model checkpoint update. If evaluation metrics detect semantic drift, accuracy degradation, or latency spikes, our prompt engineers rapidly recalibrate few-shot examples and system instructions to restore baseline performance.
Partnering with an experienced prompt engineering company ensures your models are architected with production-grade guardrails, systematic hallucination mitigation, automated regression testing, and measurable token cost optimizations that ad-hoc prompt writing cannot deliver.
Our LLM prompt engineering services design modular reasoning chains, dynamic few-shot retrieval, and strict JSON schemas, enabling next-generation reasoning models and autonomous agent swarms to execute complex multi-step workflows without logic drift or context dilution.
Comprehensive enterprise prompt engineering and AI prompt engineering services deliver measurable ROI by increasing model output accuracy by up to 42%, enforcing deterministic Pydantic schema validation for backend APIs, reducing recurring token expenditures by 30% to 50%, and defending production systems against prompt injection threats.
Didn't get an answer?
We will reach out to you in less than 2 hours!
Start Building High-Accuracy AI Systems
Turn your AI into a reliable, context-aware system with specialized AI prompt engineering services tailored to your business workflows.

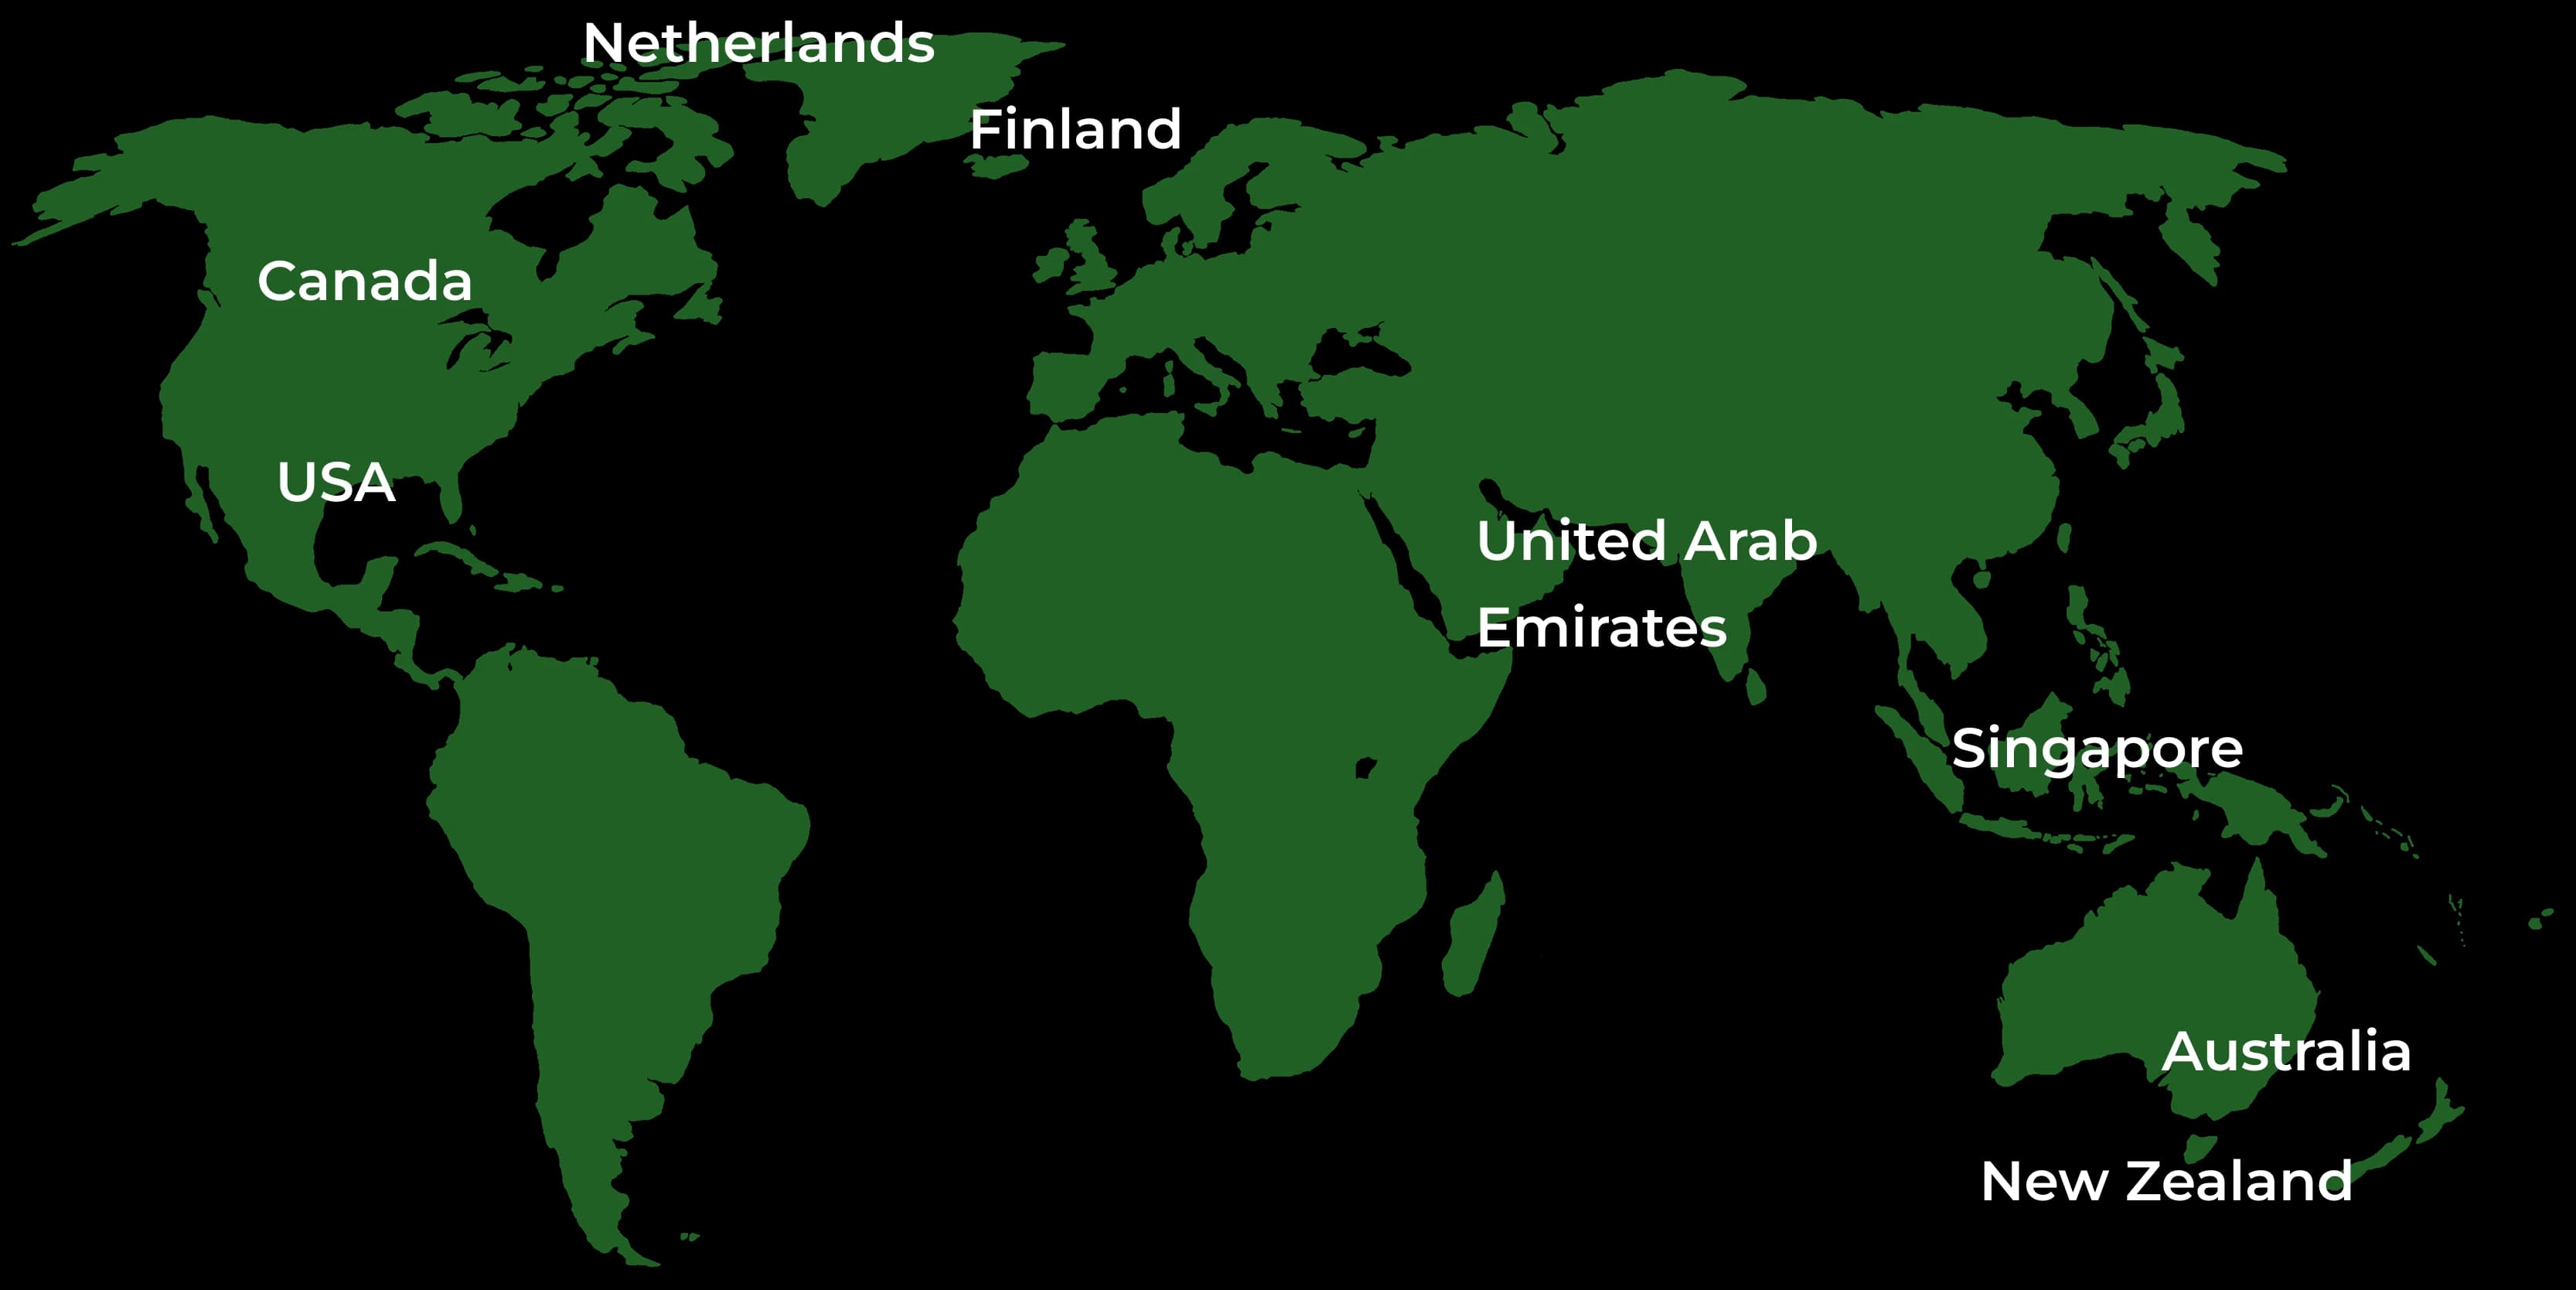
Serving in 30+ countries for AI development
United States (USA), United Kingdom (UK), Singapore, Germany, Canada, Australia, Ireland, Dublin, New Zealand, Netherlands, Norway, United Arab Emirates (UAE), Saudi Arabia, Qatar, Finland, Mexico, Switzerland, Spain, France, etc.

Trusted partner on
Clutch


Top-rated on
Trustpilot
